Hackathon · Sep 2026
Amazon ML Challenge 2026
Matching 1.7 million businesses across three noisy data sources in the US, India and France.
- Result5th on the public leaderboard
- TeamClauders, with Arush Sharma and Vaibhav Chavhan
- Validation F0.50.992 US · 0.993 India
Problem
For each of 1.7 million business entities, find every matching record in two other sources. The sources disagree on spelling, addresses and formatting, and some records are planted lookalikes.
Scoring is macro F0.5, which weights precision over recall. The final model had to be under 8B parameters and openly licensed, and France had no training labels.
What we built
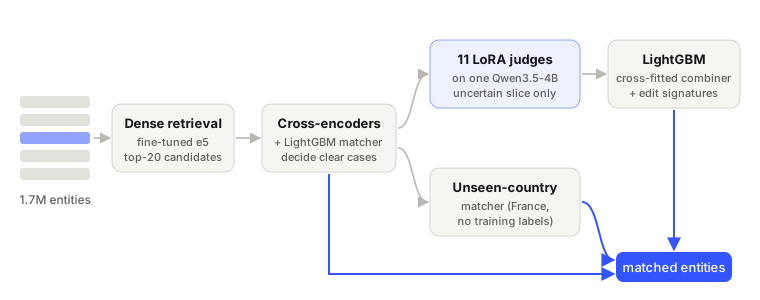
- A fine-tuned multilingual e5 retriever that pulls 20 candidates per entity. The true match is in those 20 for over 99.4% of records.
- Cross-encoders and a LightGBM matcher that settle about 93% of US and India records.
- Eleven LoRA judges on one shared Qwen3.5-4B that re-decide the uncertain slice, about 600K records.
- A LightGBM combiner with edit-signature features, such as a truncated house number or swapped words, so typos are kept and lookalikes dropped.
- A separate branch for France, built from label-free rules and cross-country judges.
Design choices
- Expensive models run only on the uncertain slice; cheap ones handle the clear majority.
- One base model with an adapter per judge kept the whole pipeline under the 8B limit.
Result
5th on the public leaderboard. Validation F0.5 of 0.992 in the US and 0.993 in India.