Project · 2026 · in progress
AlignmentLab
Does reinforcement learning with verifiable rewards teach a model anything, or would any reward do?
- ModelQwen3-8B
- MethodGRPO with matched compute
- WithArush Sharma
Problem
Papers report gains from RL on maths, but those gains can come from extra compute rather than from the reward. To tell them apart, the reward has to be the only thing that changes.
What we built
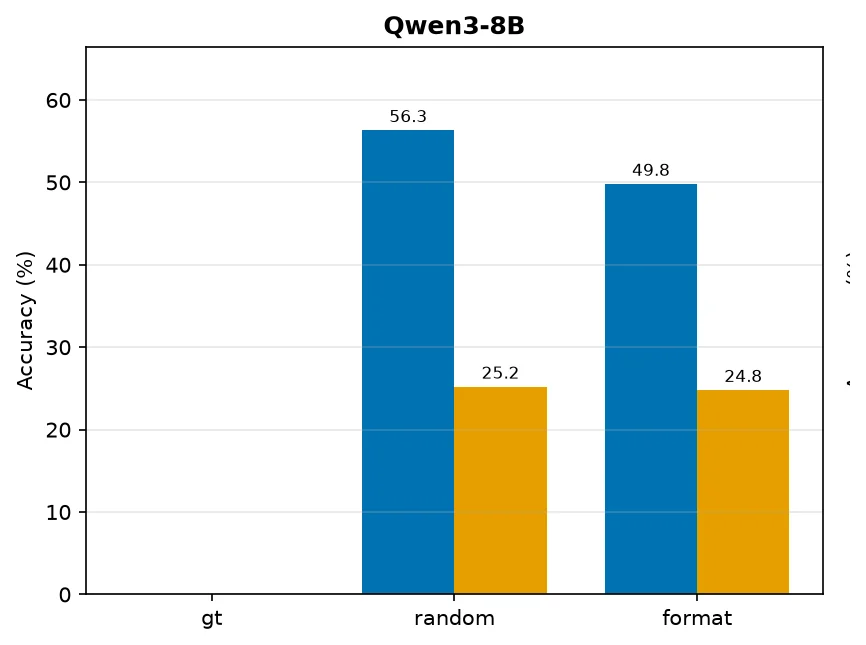
- Three GRPO runs from the same SFT checkpoint with the same data, steps and settings. Only the reward differs: correct answer, a coin flip, or just the right format.
- SFT on Tülu 3, then GRPO on 45K maths prompts, with OpenRLHF, vLLM and DeepSpeed on H200 GPUs.
Design choices
- Everything except the reward is held fixed, so any difference is the reward's doing.
Result
Rewards that ignore correctness make the model worse. GSM8K falls from 0.86 to 0.56 with a random reward and to 0.50 with a format-only one; MATH-500 falls from 0.43 to 0.25.
The correctness-reward run is being re-run.