Project · 2026 · WACV 2027
VID-CURATOR
Answering questions about long videos when you can only show the model a few frames.
- PaperWACV 2027, Applications Track
- ModelsQwen2.5-VL, Qwen3-VL, InternVL3.5
- WithAman Verma
Problem
A video model can only take so many frames. Which ones it sees decides whether it can answer, and most systems just sample them evenly.
What we built
- A loop that probes the video, retrieves candidate moments, curates a small set of frames and then answers, under a hard frame budget.
- A curator trained with GRPO that is rewarded for answering correctly with fewer frames.
- Comparisons against published frame selectors at the same number of visual tokens, on six benchmarks.
Design choices
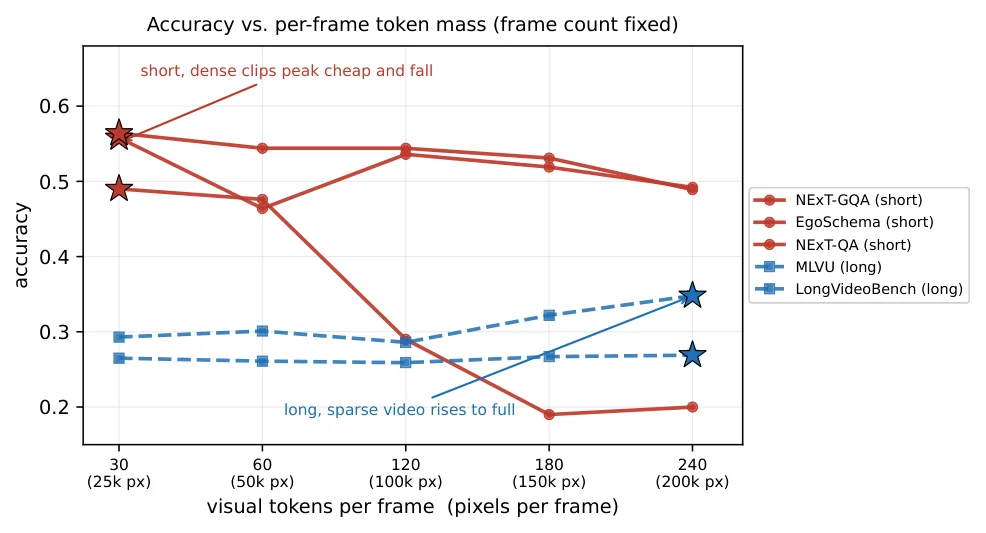
- Frame selectors are compared at equal visual tokens, not equal frame counts, since frame counts hide a 4× spread in tokens.
Result
Eight curated frames beat sixteen evenly spaced ones on NExT-GQA (0.651 vs 0.616).
The paper shows that most of the accuracy lost to extra frames is a decoding artifact: reading the answer's probability directly cuts the loss from 0.139 to 0.014.