Project · 2025
Medusa decoding
Generating several tokens per step with Medusa heads on Vicuna-7B.
- ModelMedusa Vicuna-7B
- TaskHindi to English translation
- CourseCS 726, IIT Bombay
Problem
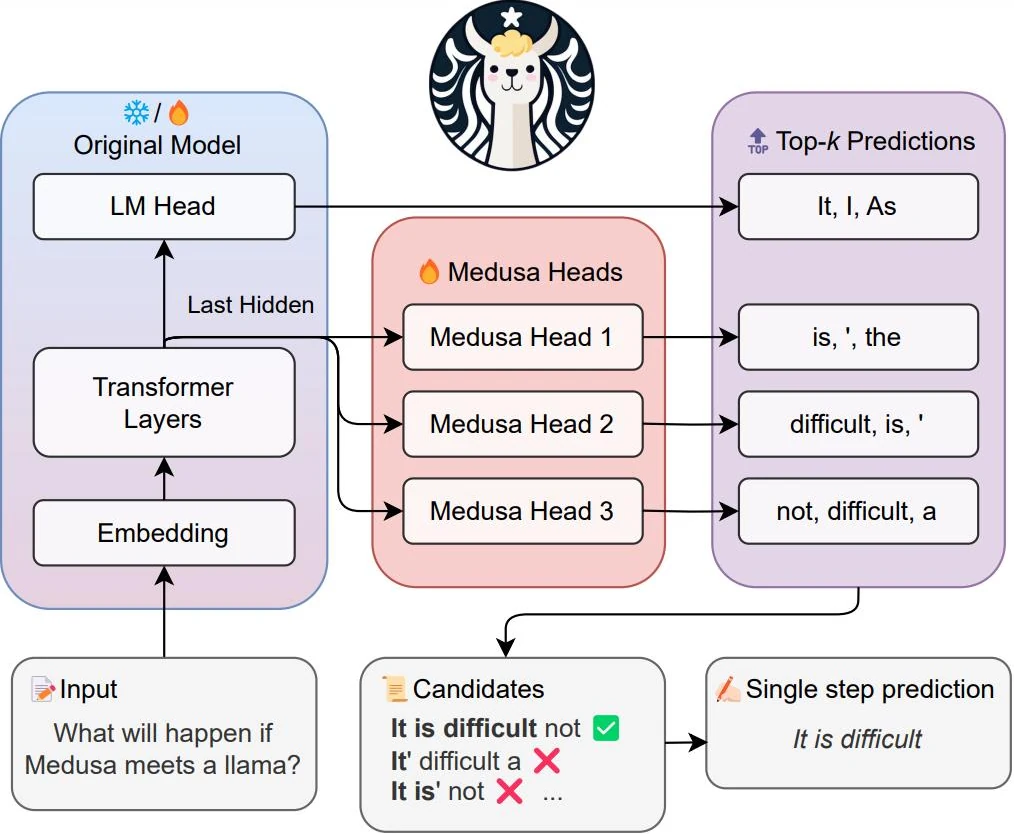
A language model writes one token per forward pass, so long outputs are slow. Medusa adds extra heads that guess the next few tokens, so one pass can produce several.
We implemented decoding from Medusa: Simple LLM Inference Acceleration Framework with Multiple Decoding Heads (Cai et al., 2024) on a released Medusa checkpoint.
What we built
- A text generator with two modes: single-head decoding and multi-head decoding with beam search.
- Evaluation on Hindi to English translation with BLEU, ROUGE and real-time factor, sweeping beam widths and head counts.
Design choices
- Wider beams and more heads trade speed against translation quality; the sweep maps that curve.
Result
Multi-head decoding ran at a real-time factor of 0.03 against 0.07 for single-head decoding, 2.3× faster. Team of three; I implemented multi-head decoding and wrote the report.