Project · 2026 · in progress
Linguistically Guided MTP
Is multi-token prediction harder in some languages because of the tokenizer or because of the grammar?
- LanguagesHindi, romanised Hindi, English
- ModelLlama-3.2-1B with MTP heads
- CourseCS 769, IIT Bombay
Problem
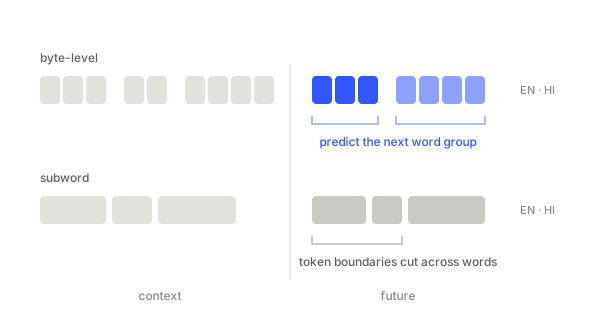
Multi-token prediction helps byte-level models and hurts subword ones, but every result so far is in English. Comparing two languages changes the tokenizer's fertility and the morphology at once.
Writing Hindi in Latin script changes how many tokens a word takes while keeping its grammar, which separates the two.
What we built
- A fertility ladder: Hindi in Devanagari, romanised Hindi and bytes, with English controls.
- Measurements that need no training: how independent the next few tokens are, and how often they finish a word.
- Four MTP heads on Llama-3.2-1B with a shared trunk, trained on 10M tokens per condition.
Design choices
- One backbone for every condition, because the choice of model moved the measurements twenty times more than the script did.
Result
So far, how often the next tokens finish a word follows fertility, not script: 0.30 for both Hindi scripts against 0.72 for English. Training runs are under way.